


Teacher evaluation should improve teaching, not create a popularity contest

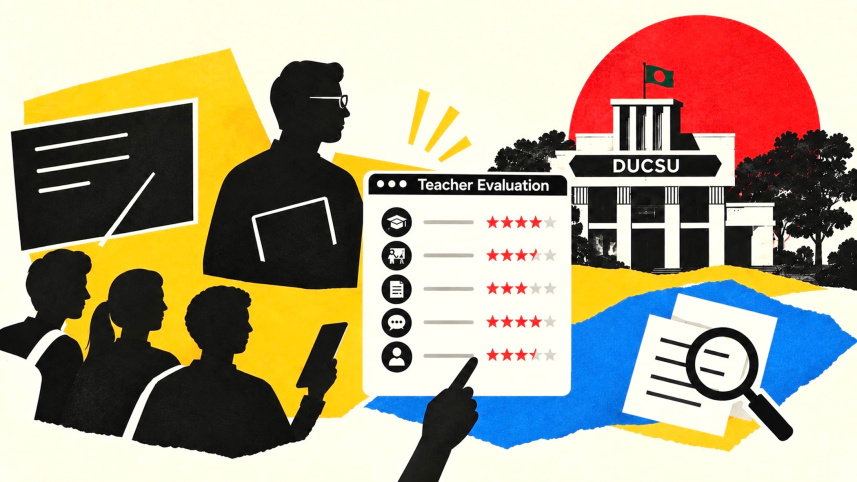
Teachers should be evaluated, but should they be publicly ranked? This distinction lies at the heart of the controversy surrounding the online platform recently launched by the Dhaka University Central Student Union (Ducsu) for evaluating teachers at Dhaka University. There, students can anonymously assess teachers in their departments on matters such as course organisation, teaching methods, assessment, communication, and professionalism. Numerical ratings and written comments are then made accessible.
The initiative, we must admit, is a response to a genuine institutional failure. Students are consistently evaluated through attendance, assignments, presentations, examinations and viva voce. But teachers rarely receive systematic feedback from those who experience their teaching. Some teachers collect such feedback voluntarily, but the university has not maintained a regular and credible system across departments.
The Ducsu controversy thus serves to bring a neglected issue into the discussion. Students have a legitimate interest in the quality of their education. They are also well-placed to report whether a teacher attends classes regularly, comes prepared, explains ideas clearly, provides useful feedback, assesses fairly, and treats students with respect. However, feedback and public ranking are different things. The first can improve teaching; the second may reduce a complex educational relationship to a competition for stars. So three questions must be separated here: i) who has the authority to evaluate teachers; ii) how reliable the evidence being collected is; and iii) what the evaluation system will do to the practice of teaching.
The first is a question of institutional responsibility. The DU authorities have argued that formal teacher evaluation falls outside Ducsu’s jurisdiction, and that the university has approved its own policy and plans to implement it from the 2026-27 academic year.
Ducsu cannot acquire institutional authority simply because the university administration has acted slowly. It can represent students, collect their concerns, and pressure the university to introduce evaluation. But a system affecting professional reputations requires established rules concerning evidence, privacy, moderation, correction and appeal. Those rules cannot be improvised after ratings have already been published. That said, the administration should also answer: if an approved evaluation policy exists, why has it not been implemented yet? And what prevented earlier initiatives from becoming permanent? When precisely will the new system go live, and how will students participate in its design? Institutional authority carries institutional responsibility.
The second question concerns the quality of the evidence. Giving every student a voice does not mean that every submitted judgement provides equally strong evidence. Authentication through a DU email can establish that a reviewer is a university student and restrict evaluation to the student’s department. It does not establish that the student completed a particular teacher’s course, attended it regularly, or possesses sufficient experience to evaluate that teacher. Departmental affiliation is not the same as course-level knowledge.
Voluntary participation creates another difficulty. Students with exceptionally positive or negative experiences may be more motivated to submit reviews than those with moderate views. If five students respond from a class of 100, their experiences deserve to be heard. But their average cannot reasonably be presented as the judgement of the class. A score such as 1.8 or 4.7 may look precise, but its decimal point does not make the underlying evidence representative.
The problem goes beyond sample size. The idea of the “wisdom of crowds” works only under certain conditions. Respondents must possess relevant knowledge, and their judgements must contain some degree of independence and diversity. One hundred reviews do not necessarily constitute 100 independent pieces of evidence. Students may repeat the same allegation, share a political prejudice, participate in a coordinated campaign, or respond collectively to strict grading. When the same information or bias is counted repeatedly, numerical agreement can create an illusion of reliability.
The lesson here is not that some students should be denied a voice, but that equality of participation and equality of evidential weight are different principles. A student who attended a course regularly and evaluated specific aspects of it possesses a different evidential basis from someone reacting to hearsay, departmental politics or a disputed grade. Nor can students determine every dimension of teaching equally well. They possess strong first-hand evidence about punctuality, clarity, accessibility, respectful conduct and the relationship between classroom content and examinations. They may be less well-placed to determine whether a syllabus adequately represents a discipline, whether a difficult course produces long-term intellectual development, or whether teachers working in different fields and contexts can validly be compared.
International research provides additional reasons for caution. Student evaluations can be influenced by expected grades, workload, course difficulty, and characteristics of the teacher that are unrelated to teaching effectiveness. Research has also detected gender bias in such evaluations. This does not necessarily make student testimony worthless, but it does show why it must be interpreted rather than merely aggregated.
The third question is deeper: what will public scores do to teaching itself?
Philosopher C Thi Nguyen has argued that scoring systems do not merely measure human activities but can change their goals as well. Rich and plural values are replaced by simplified targets, and people gradually begin pursuing the score rather than the good the score was meant to represent. Good teaching involves knowledge, preparation, clarity, intellectual challenge, fair assessment, responsiveness, integrity and respect. No single number can represent all these goods adequately. But once a public score becomes professionally or socially important, teachers may feel pressure to optimise for it. A teacher who assigns less work, gives higher grades, or avoids difficult and unpopular material may receive better ratings than one who maintains demanding but fair standards. That the system may measure teaching badly is not the issue here; the bigger concern is that it may change teaching for the worse by creating incentives to become more popular rather than more effective.
It may also change how students understand their role. Students are not simply consumers rating a service provider; they are participants in a shared educational practice. Teachers have duties to prepare, teach seriously, assess fairly and respect students. Students also have duties to attend, read, think, participate and judge responsibly. Evaluation should strengthen this relationship, not replace it with the consumer logic used for restaurants, hotels and ride-sharing services.
Anonymous feedback remains necessary because of the power imbalance between teachers and students. But anonymous feedback differs from anonymous public accusation. Comments about unclear explanations or delayed feedback are pedagogical judgements. Allegations of corruption, political misconduct or personal wrongdoing require a different evidential standard. When such claims are publicly attached to an identifiable teacher, there must be moderation, a right of reply, and a transparent appeal process.
The alternative, as stated before, is not to silence students. Student feedback should be collected at the course level from verified students. Response rates and minimum thresholds should be disclosed. Questions should address specific conduct rather than invite vague judgements of popularity. Written feedback should ordinarily remain confidential, while serious allegations should be handled through a separate complaints mechanism. Most importantly, student feedback should be one part of a broader framework that includes peer observation, course and assessment review, teaching portfolios, and evidence of student learning. Its primary purpose should be diagnosis and improvement. Professional consequences should follow only when the evidence is sufficiently robust and due process is guaranteed.
It’s high time public universities in Bangladesh, including the DU, created a credible system of evaluation. Teachers should not fear accountability, and accountability is not achieved merely by making judgement public. The purpose of evaluation is to help every teacher teach better and every student learn better. If the score becomes the goal, evaluation no longer serves education—education begins to serve the score.
Dr Kazi ASM Nurul Huda is associate professor of philosophy at Dhaka University and Zuzana Simoniova Cmelikova Visiting International Scholar in Leadership and Ethics at Jepson School of Leadership Studies in the University of Richmond, US. He can be reached at huda@du.ac.bd.
Views expressed in this article are the author's own.
Follow The Daily Star Opinion on Facebook for the latest opinions, commentaries, and analyses by experts and professionals. To contribute your article or letter to The Daily Star Opinion, see our guidelines for submission.
 For all latest news, follow The Daily Star's Google News channel.
Comments